Research

OpsBench: A Reliability-Oriented Benchmark for Open-Weight Agents on Internal Enterprise Operations

Willy Fitra Hendria

NeurIPS 2026 Workshop on Agentic AI Benchmarks and Applications for Enterprise Tasks (AABA4ET), 2026 (accepted)

A dialogue-driven, reliability-first benchmark for open-weight agents on internal IT-helpdesk work.
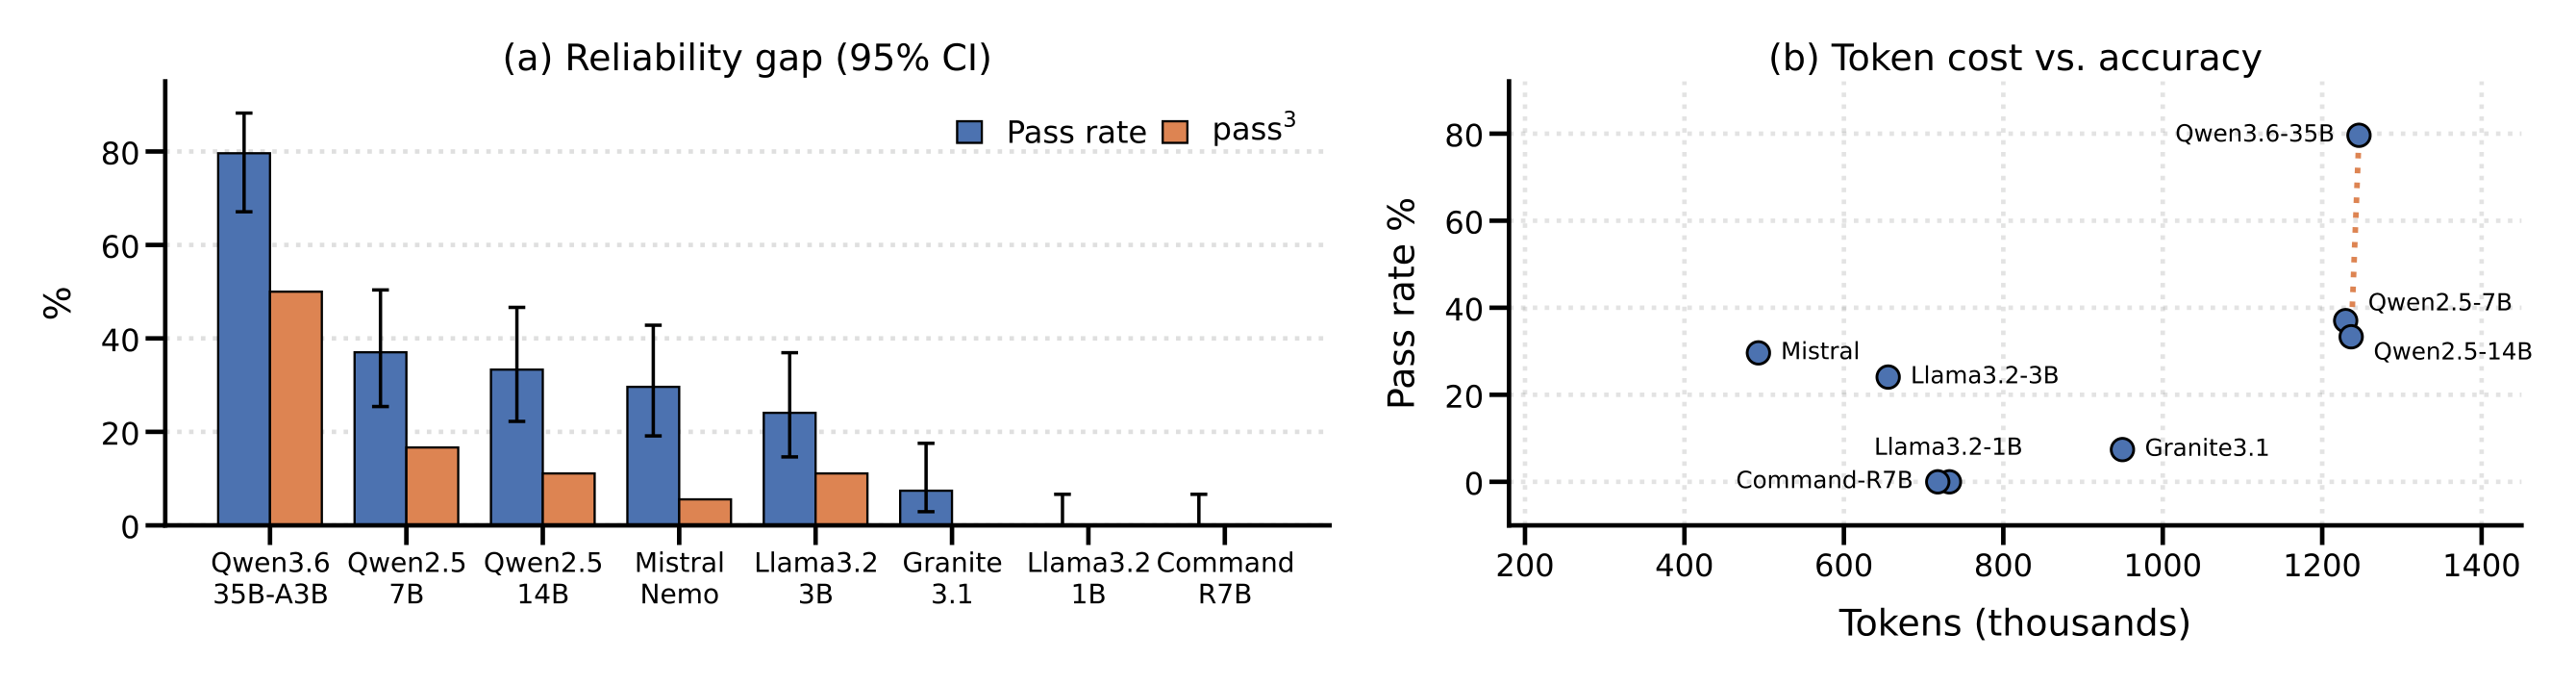
Two charts. (a) Pass rate and pass^3 with 95% confidence intervals for eight open-weight models: Qwen3.6-35B-A3B reaches about 80% pass rate but 50% pass^3; Qwen2.5-7B, Qwen2.5-14B, Mistral Nemo and Llama3.2-3B fall between 24% and 37%, with much lower pass^3; Granite 3.1 reaches about 7% pass rate with zero pass^3; Llama3.2-1B and Command R7B score zero. (b) Pass rate against token cost in thousands of tokens, from about 490k to 1,250k.