Research

Papers, preprints and technical reports, with code wherever we can share it.

OpsBench: A Reliability-Oriented Benchmark for Open-Weight Agents on Internal Enterprise Operations

Willy Fitra Hendria

NeurIPS 2026 Workshop on Agentic AI Benchmarks and Applications for Enterprise Tasks (AABA4ET), 2026 (accepted)

A benchmark for how reliably open-weight agents carry out internal enterprise operations. Across eight models, the strongest, Qwen3.6-35B-A3B, passes about 80% of tasks but succeeds on all three attempts (pass3) only 50% of the time, and three smaller models solve none.
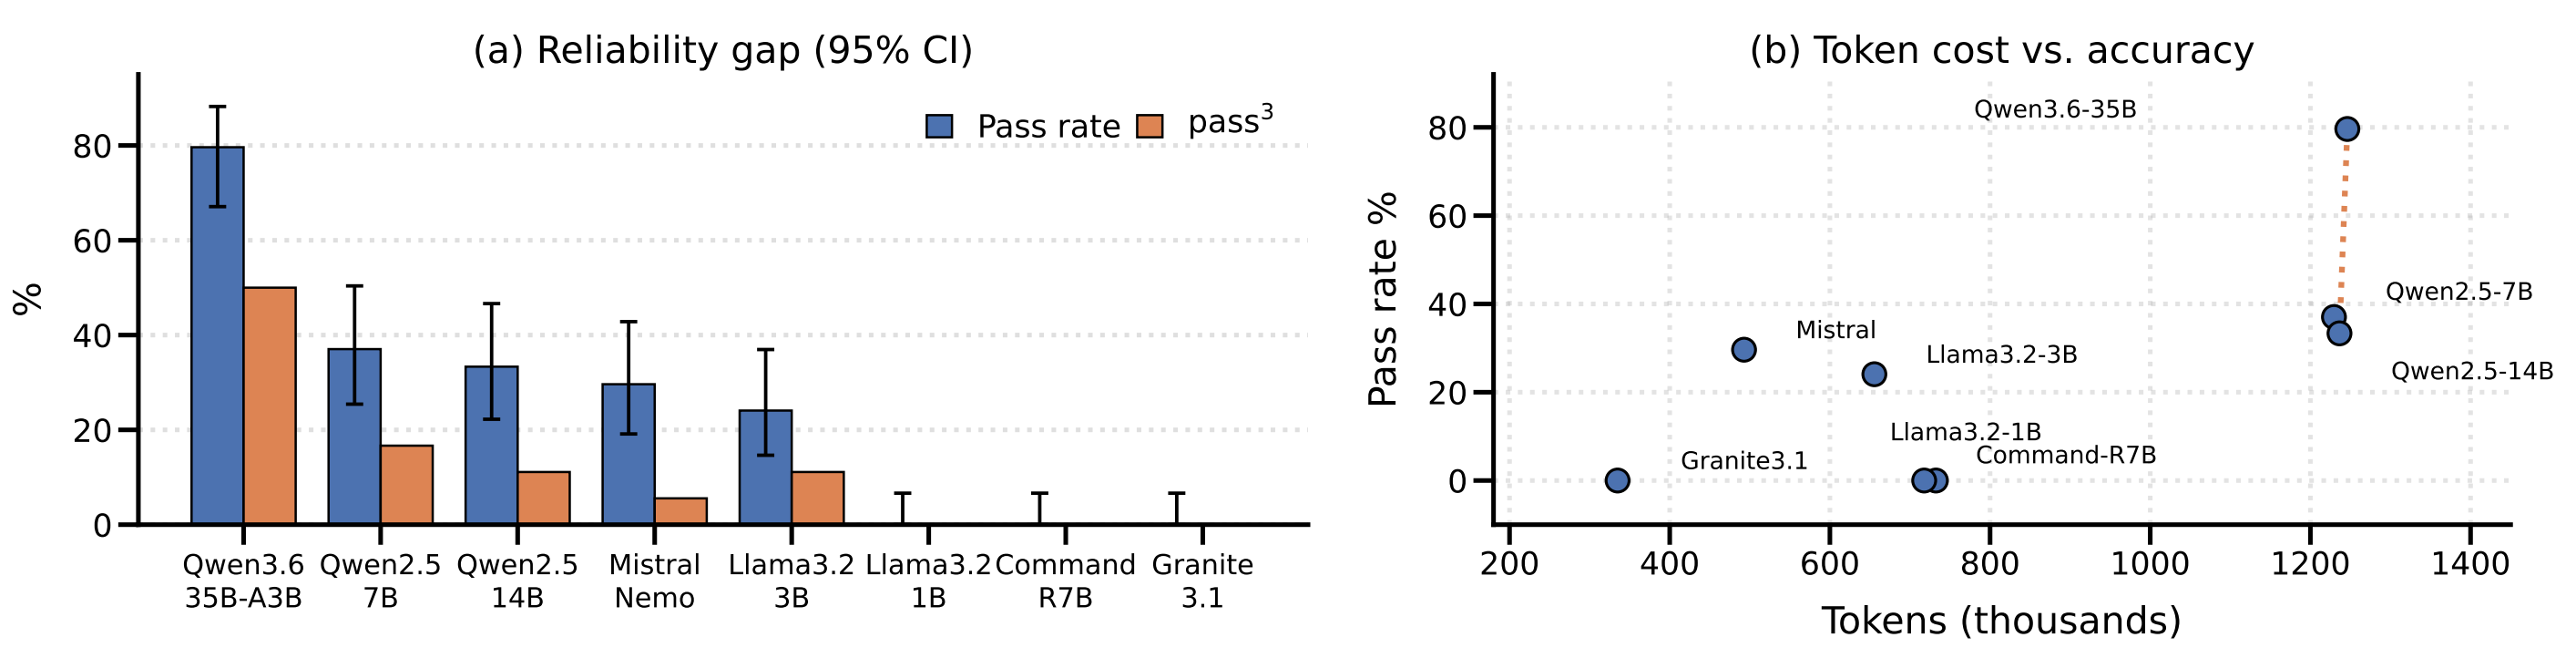
Two charts. (a) Pass rate and pass^3 with 95% confidence intervals for eight open-weight models: Qwen3.6-35B-A3B reaches about 80% pass rate but 50% pass^3; Qwen2.5-7B, Qwen2.5-14B, Mistral Nemo and Llama3.2-3B fall between 24% and 37%, with much lower pass^3; Llama3.2-1B, Command R7B and Granite 3.1 score zero. (b) Pass rate against token cost in thousands of tokens, from about 330k to 1,250k.